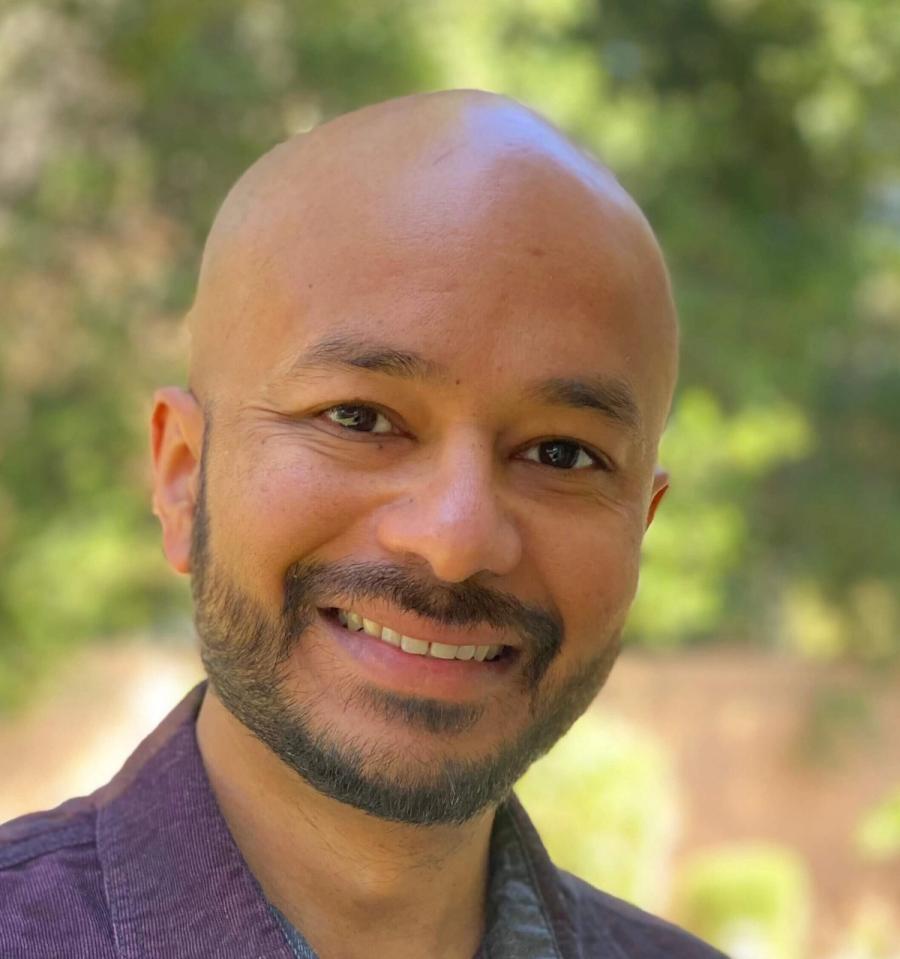
Shirshanka Das

Co-Founder and CEO, Acryl Data

Shirshanka is co-founder and CEO of Acryl Data, the company which is commercializing the open source DataHub project, a real-time metadata platform used by LinkedIn, Stripe, Pinterest, Optum, Expedia and many others. Prior to founding Acryl, he was the overall architect for Big Data at LinkedIn from 2010 to 2020, and responsible for creating the metadata and data management strategy at the company. As part of this, he founded the DataHub project and shaped its evolution to a metadata platform that powers DataOps, MLOps, productivity, and governance use cases at LinkedIn. He is also a PMC and committer on the Apache Gobblin project which manages 100PB+ of data assets at rest at LinkedIn, and is deployed in production at other large companies like Verizon, PayPal etc. Prior to LinkedIn, Shirshanka worked on high-performance serving systems at Yahoo and PayPal. Shirshanka has a Ph.D. in Computer Science from UCLA.

Shirshanka Das

Sessions / 2023 / 1 talk

  • Keynote: March 28th @ 9:00am Data Discovery, Data Observability, Data Quality, Data Governance, Data Management have traditionally been addressed as individual problems with distinct solutions. However, business challenges like access management, data retention, cost attribution and optimization, and end-to-end data quality require these tools to work together. Without a harmonizing layer across systems, these issues are impossible to manage in a uniform manner across the stack. We are calling this harmonizing layer the ‘Control Plane for Data’ - powered by the common thread across these systems: Metadata. In this talk, we’ll describe what the control plane of data looks like and how it fits into the reference architecture for the deconstructed data stack: a data stack that includes operational data stores, streaming systems, transformation engines, BI tools, warehouses, ML tools and orchestrators. We’ll dig into the fundamental characteristics for a control plane: Breadth (completeness) Latency (freshness) Scale Source of Truth Auditability We’ll discuss what use-cases you can accomplish with a unified control plane and why this leads to a simpler, more flexible data stack. Finally, we’ll share thoughts on how the industry should evolve to enable this vision and how a constellation of projects including DataHub are working towards making this a reality. If you’re a data leader that has accumulated a ton of specialized data tools in a short amount of time and are wondering how to restore order back into your data teams’ daily lives, this talk is for you.

Sessions / 2022 / 2 talks

  • Datasets are one of the fundamental concepts in data work: as data practitioners, we use the word all the time in colloquial day-to-day conversations. Many different data tools have independently converged on similar concepts. However—like many concepts in the modern data stack—the exact meaning, properties, and capabilities of Datasets differ in subtle but important ways. Concepts like Datasets will define the next generation of data work. The cornerstone of “the modern data stack” is a new set of tools, abstractions, and metadata that map more tightly to the real work that data practitioners need to do. This panel brings together leading tool builders and practitioners in the data community to discuss that evolution. We’ll start by comparing and contrasting different approaches to Datasets. From there, we’ll branch out into an open discussion about relative strengths and weaknesses of different approaches, and alignment (or lack thereof) between tools and systems. This talk will be useful for data practitioners looking to understand how the field is evolving, and how new tools are enabling those changes.

  • Ever wonder what is the secret behind the productivity of data scientists and engineers at data-driven companies like LinkedIn, Airbnb, and others? The answer lies in delightful and trustworthy data discovery! In this session, Shirshanka Das and Maggie Hays walk you through one of the most popular data discovery systems in the open-source data space, DataHub. We will share how DataHub stitches together metadata from tools like dbt, Airflow, Spark, Looker, and many others to create delightful data discovery experiences at many companies like LinkedIn, Expedia, Peloton, Saxo Bank, and Wolt. After taking a peek under the hood of DataHub’s architecture, we’ll show you how to get productive with DataHub in 10 minutes or less. We will share approaches to automation that we have heard from the almost 2K strong DataHub Community, as well as strategies for sourcing and surfacing impactful metadata to fuel data discovery, modern data governance, and data observability.

Ready to take this stage?

The next edition is programmed by practitioners. Tell us what you built and what you learned.

Apply to be a speaker