All 2026 AI Council sessions in one place — filter by topic, speaker, or company.
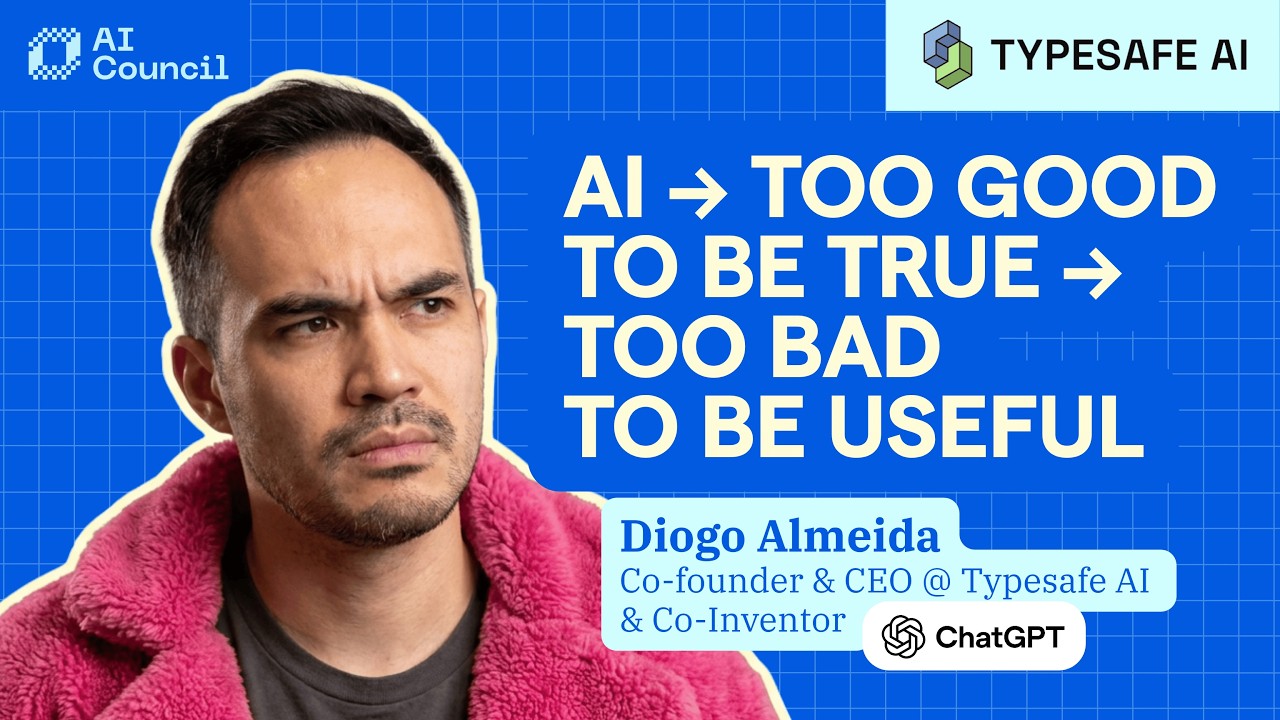
AI: Too Good to Be True, Too Bad to Be Useful
Four months before TypeSafe AI launched Jev, founder Diogo Almeida stood up at AI Council and laid out the problem Jev was built to solve. He never names the product in this talk. He says only that TypeSafe is going all in on automation and getting ready to ship in a couple of months, then spends 36 minutes on why he thinks the rest of the field is pointed the wrong way. TypeSafe came out of stealth on September 15, 2026 with $40M led by DCVC and launched Jev, a model that outputs typed decisions with probabilities for software to act on. Almeida spent four and a half years at OpenAI, where he co-authored the InstructGPT paper and the GPT-4 Technical Report and worked on the RLHF research behind ChatGPT. His argument here starts from that work. His read is that roughly all production LLMs are trained with RLHF or some variation of it, and RLHF optimizes for human preference. Human preference is a different target from doing the task correctly. That gap is why AI looks superhuman on assistance work and falls apart on automation work that looks easier. He walks through mode collapse, Yann LeCun's doomed-LLM argument, why a 1.3B-parameter InstructGPT model was preferred to 175B GPT-3 at following instructions, and where he thinks Sutton's bitter lesson is incomplete. He closes on the question that started TypeSafe, which is what it would take to treat language models as a primitive that software calls, the way it calls a database or an API.
All Talks
Explore every session from AI Council 2026, and to see past year's talks visit our YouTube channel.
AI Launchpad 2026: Pavo
Pavo builds systems-first intelligence for the enterprise: self-evolving knowledge systems, agent societies, and world models that learn from experience to optimize business outcomes.

AI Launchpad 2026: Mixtrain
Mixtrain provides infrastructure for the full post-training lifecycle, spanning data curation, training, evaluation, and deployment.
AI Launchpad 2026: Golden Analytics
Golden Analytics is an AI-native business intelligence (BI) platform designed to automate mechanical data tasks like data prep, visualization, and presentation generation.

AI Launchpad 2026: CocoIndex
CocoIndex fills the gap of context layer for AI where it continuously takes source and transforms it incrementally on source change or logic change to serve live AI agents, at scale.

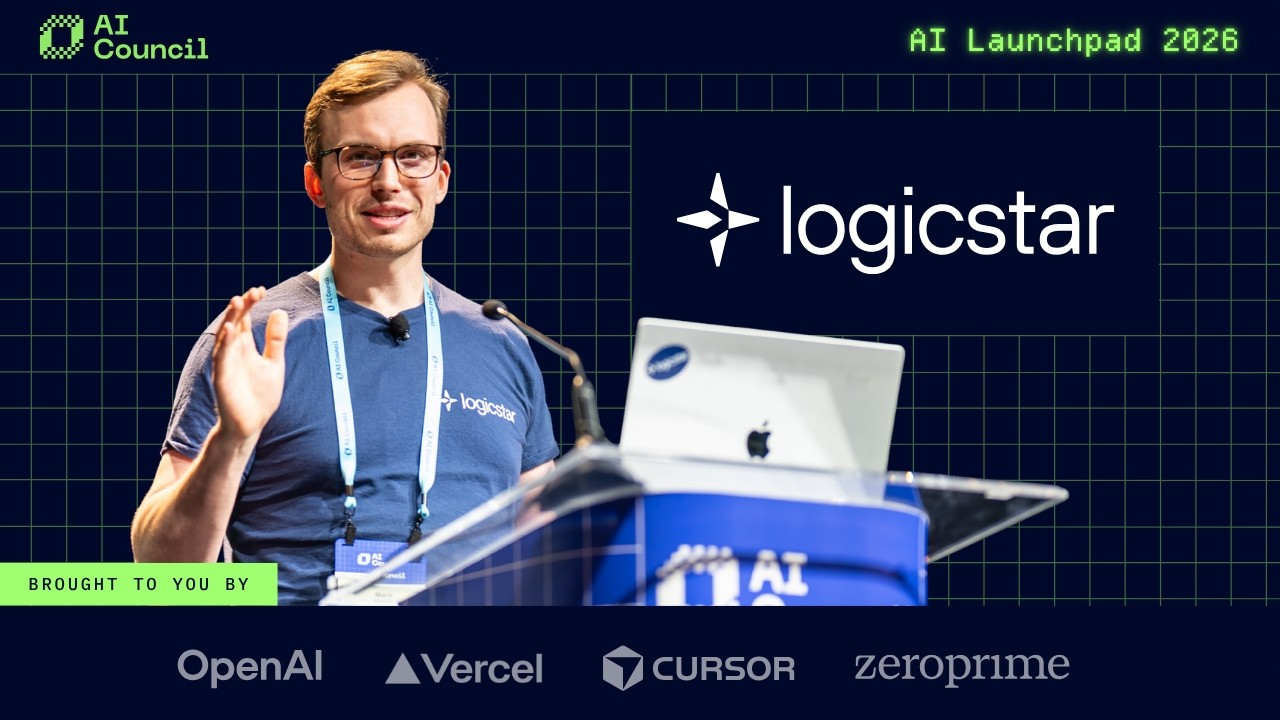
AI Launchpad 2026: LogicStar AI
LogicStar finds, investigates, and resolves code issues that matter before they become incidents.
AI Launchpad 2026: Sutro
Sutro enables AI teams to build high-volume, expert-aligned models they can trust at scale, reducing manual review time by 90% and inference costs by 80%.
Inference for Async Agents in Production
As models improve, we are starting to build long-running, asynchronous agents such as deep research agents and browser agents that can execute multi-step workflows autonomously. These systems unlock new use cases, but they use orders of magnitude more tokens and compute, creating scaling bottlenecks. This talk discusses practical strategies builders can use to maximize async agent performance while keeping inference costs under control. Topics covered include context engineering, compaction, cache maintenance, model routing, and batch inference. This talk is aimed at use case developers, with secondary relevance to platform engineers.
Running Millions of (Millisecond) AI Sandboxes without Breaking the Piggy Bank
Agents are great, but they place difficult requirements on the underlying infrastructure they run on: (1) they need to be strongly isolated (eg, within a VM); (2) they need to start up as quickly as possible (ideally in milliseconds) and put to sleep when not used; and (3) they require massive scale (eg, millions of them for even a single provider/product). Using standard infra to run sandboxes at this level of scale can result in eye-watering cloud-infra bills. And attempting to start sandboxes in milliseconds is an unsolved challenge. In this talk we’ll cover our years-long journey aimed at severely optimizing and increasing the efficiency of how workloads are deployed on the cloud, beginning with research and OSS work. Along the way, we’ll cover the basics of virtualization and isolation primitives (e.g., virtual machines, microVMs, containers, isolates) and their performance and security trade-offs. With that in place, we will describe how we leveraged the research and OSS work to build a virtualization system that can start any workload in a few milliseconds, and cram up to 1M+ such lightweight VMs into a single, off-the-shelf server, allowing for millions of strongly-isolated agents to be hosted in a rack, rather than an entire data center. Finally, we will show a brief live demo of this in action.

Do the Boring Stuff to Make Open Source AI Win
"Open source AI just isn’t as good as OpenAI, Anthropic, and Gemini.” Needing to reach performance parity with closed source frontier models is the prevailing north star for open source AI - and this is an important goal! Here, I’ll make the case for a different north star: ease of use. Open source AI can win if it becomes dead easy to use, the simple default option for the 99% of AI use cases that don’t require the newest frontier mega-model. The missing piece is being so easy to install, maintain, and use that customers aren’t tempted to default elsewhere. That means our community moving beyond benchmarks to beautifying UI/UX, reducing jargon, building catchy apps, and meeting the modal end-user where they are - *not* just on GitHub or Hugging Face, but rather in the address bar of a browser or the app store. Throughout, I’ll talk about some of the decisions we are making at Mozilla to support our “choice-first stack,” a portfolio of commercially-licensed open source AI projects meant to take steps toward making open source AI more approachable, maintainable, and usable.
Agents will need trillions of databases. Let's give it to them!
The same way computing for agents is evolving into sandboxes, data infrastructure for agents will necessitate the provisioning and maintenance of trillions of databases. From agent memory, session data, to the mind-boggling number of databases vibe-coded applications will need, it is clear we need databases that come online instantly and are individually cheap. SQLite is widely acknowledged to have the right shape for this, but it also at the same time lacks the extended feature set that modern applications need. In this talk we will present Turso, an open- source rewrite of SQLite in Rust, that keeps full compatibility with its file-based nature while expanding what it can do.
Showing 10 of 86