A look back on 2024
The talks that shaped AI Council 2024.


2024 Featured Talks
Highlights from AI Council 2024 — the talks that defined the year.

Processing Trillions of Records at Okta with Mini Serverless Databases
Jake Thomas · Okta
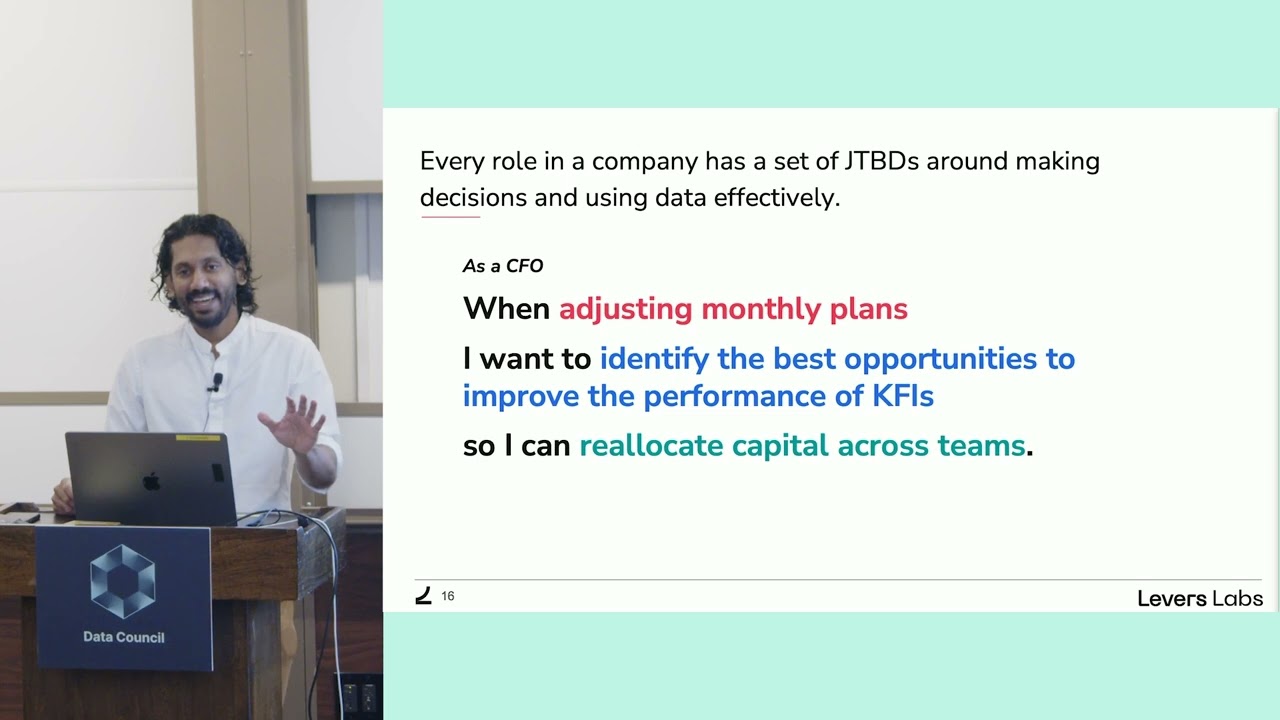
Data Culture as a Product
Abhi Sivasailam · Levers Labs

The Future Roadmap for the Composable Data Stack
Wes McKinney · Posit

Building InfluxDB 3.0 with Apache Arrow, DataFusion, Flight and Parquet
Andrew Lamb · InfluxData
All 2024 Talks
Every session from 2024 — filter by topic, speaker, or company.
Processing Trillions of Records at Okta with Mini Serverless Databases
While building Okta’s next-gen security data platform we quickly realized pipelines needed the total cost of ownership of batch ETL, the latency of streaming, the flexibility of SQL, the durability of S3, the ease and enormous scalability of serverless, ultra-minimal footprint for constrained environments, and maximal cost efficiencies. To satisfy these requirements we turned to serverless DuckDB’s for all data preprocessing, normalization, operational metadata harvesting, and more. After processing trillions of rows over hundreds of millions of files, we are continuing to learn and find new use cases for this model. This talk will be about how we built our systems, what we’ve learned along the way, and what we are thinking about next. Do you really need Kafka in 2024? Do you want the latencies of batch ETL? Do you need the cost, complexity, and mess of ELT? Come find out!

Data Culture as a Product
Data Teams often talk about wanting to be "product" teams as opposed to "service" teams. The best way to really realize that shift is to think about every output a data team owns as a product, and to approach those products as a product manager would. In this talk, we'll explore one such "product" of a data team: the data culture of the organization. We'll approach data culture as a product growth problem and think through how to onboard, activate, and retain this product's "users" using frameworks used by the most effective growth teams. And we'll ground these practices in real initiatives that companies have used to build high-performance and truly data-driven organizations.
The Future Roadmap for the Composable Data Stack
In this talk, I plan to review the progress we have made in the last 10 years developing composable, interoperable open standards for the data processing stack, from such infrastructure projects as Parquet and Arrow to user-facing interface libraries like Ibis for Python and the tidyverse for R. In discussing the current landscape of projects, I will dig into the different areas where more innovation and growth is needed, and where we would ideally like to end up in the coming years.
Building InfluxDB 3.0 with Apache Arrow, DataFusion, Flight and Parquet
In this talk, we will describe the design of InfluxDB 3.0's new high performance timeseries database engine using Apache Arrow, DataFusion, Parquet and Rust. This design provides a fast and highly interoperable analytic system without a tightly integrated codebase built from scratch. It is part of a larger trend in database system design, so called deconstructed databases, where high performance interchange standards and high quality open source components form the foundation for high performance and highly interoperable specialized analytic systems.
Beyond Simple A/B Testing: Advanced Experimentation Tactics
A/B testing is rapidly establishing itself as a core tool in product development. In this talk, we will start with a recap of standard A/B testing, including best practices. We'll also explore cutting-edge, less-familiar but powerful methodologies which address well-known limitations of standard A/B Testing. These include Sequential Testing, Multi-Armed Bandits, Switchback Experiments, Stratified Sampling, Heterogeneous Effects Detection and Experimental meta-analysis. Designed for data professionals and product builders, this presentation aims to inspire the embrace of innovative approaches and provide insights into the frontiers of experimentation.
Panel: Data Lineage We’ve Come a Long Way
Lineage has long been a requirement for anyone processing data - whether for complying with regulations, ensuring data reliability or, to quote Marvin Gaye, plainly just knowing what’s going on from provenance to impact analysis. However, our industry has historically had difficulties collecting data lineage reliably. From the early days of lineage powered by spreadsheets, we’ve come a long way towards standardizing lineage. We have evolved from painful, manual approaches to automated operational lineage extraction across batch and stream processing. Now, we’re on the brink of a new era when lineage will be built into every data processing layer - whether ETL, data warehouse or ai - and not an afterthought. In this panel, OpenLineage project lead Julien Le Dem will ask professionals from the Data catalog and data observability space how their experience building products that rely on lineage has evolved over the past 10 years.
A 101 in Time Series Analytics with Apache Arrow, Pandas and Parquet
Columnar databases are on the rise! They provide an efficient and scalable data warehouse for many use cases including time series data. The problem? many conventional database drivers and querying methods become the bottleneck for data processing and analytics within our client-side applications. Learn how to leverage open-source projects like Apache Arrow Flight and Apache Parquet alongside industry-standard analytics libraries to build the foundations of a performant analytics application for time series data.

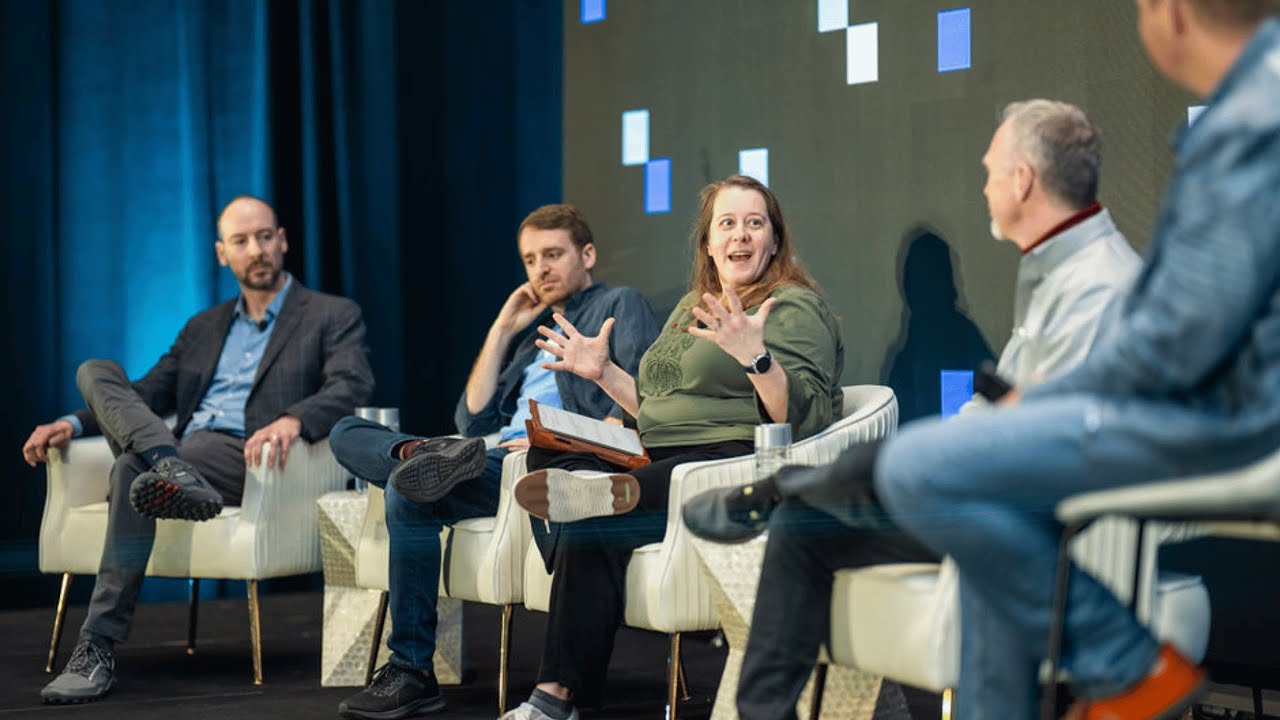
How Developers Should Think About the Emerging AI Stack
The purpose of the panel is to cover insights, challenges and opportunities in the nascent AI development stack, and to give application developers and tooling builders information on where AI development is heading, and the best ways to think about building AI-based applications deployable at internet scale.


The Future of Data Engineering in a Post-AI World
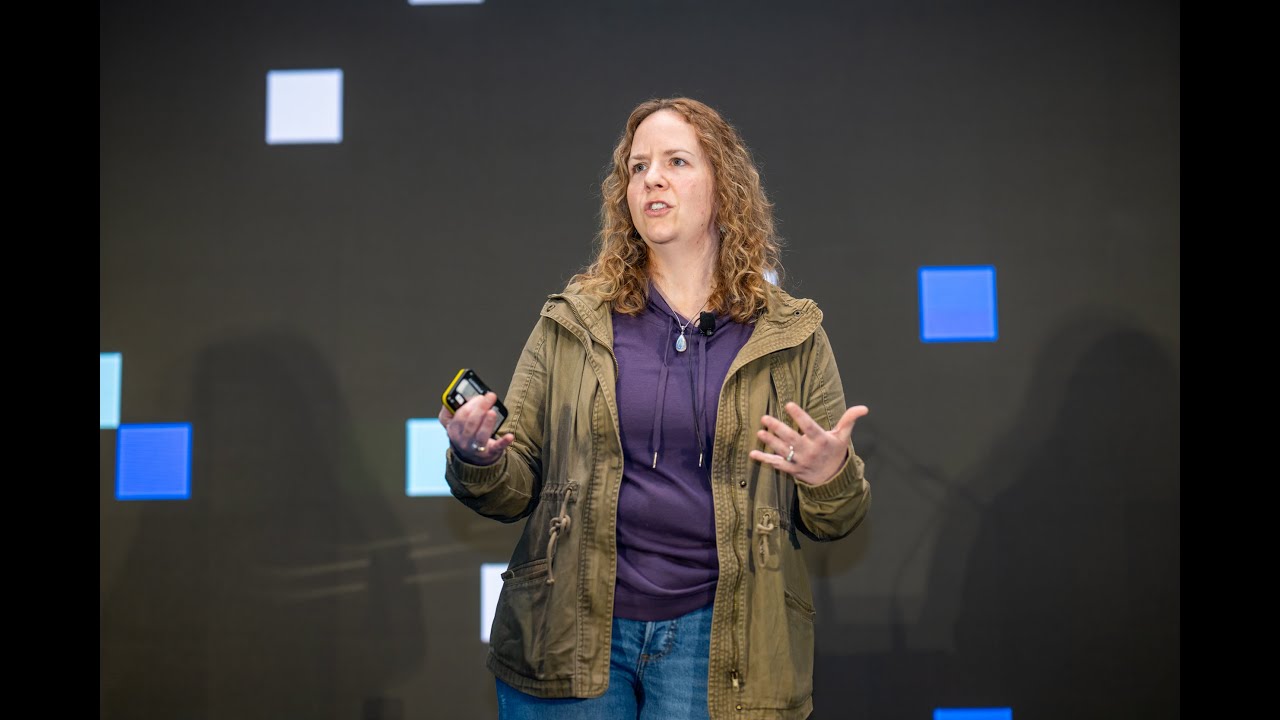
What does data engineering look like in a post-AI world? Will we even need data engineers? What will they do with their time if we can automate ETL? How does data engineering interact with AI? What is the role of data pipelines and data warehouses in a world of LLMs and vector databases? How can data engineering leverage this newfound intelligence to become betterfastersmarter? The answers to these questions and more await you in this talk by eBay Distinguished MTS Michelle Ufford. She’ll begin with a brief look at the evolution of data engineering before delving into the major new data technologies and architectural patterns enabling AI, and conclude with some ways data teams can leverage AI to grow their own business impact. This talk is ideal for data engineers wanting to future-proof their skills, data leaders needing to support and leverage AI, and anyone looking for hope and inspiration as we all speed towards an AI-fueled future.
Open Data Foundations across Hudi, Iceberg and Delta
When your data is at rest, Hudi, Delta and Iceberg are not so different yet it is increasingly hard to decide which table format to pick for your data platform. OneTable, a brand new open source project unlocks omni-directional interoperability between the popular lakehouse projects Apache Hudi, Delta Lake, and Apache Iceberg. Onetable offers lightweight conversion mechanisms that can take a source metadata format and sync it into one or more target metadata formats. This session will feature a live demo and describe real-world applications of how to build open data foundations that can accelerate your workloads into a variety of open source query engines including Spark, Presto, Trino, Flink and more. We will describe the technical foundations for Hudi, Delta and Iceberg and lay out the nuts and bolts of how Onetable seamlessly converts data between these formats. We will detail our journey to create the project, share the vision for the future and show how you can join this new open community.

Showing 10 of 84
The voices that shaped 2024
Learn from the engineers at OpenAI, NVIDIA, and Anthropic who are moving the industry forward.
A. Jesse Jiryu Davis
Senior Staff Research Engineer, MongoDB
Aaron Taylor
Chief Architect, Nalej
Adam Cimarosti
Senior Software Engineer, QuestDB
Alex Dimakis
Professor, The University of Texas at Austin
Alex Martin
Head of Product, Tinybird
Alex Wood-Doughty
Data Science Engineer, Monocle
Alexandru Cristu
Senior Solution Architect, Streamkap
Amber Roberts
ML Engineer & Community Leader, Arize AI