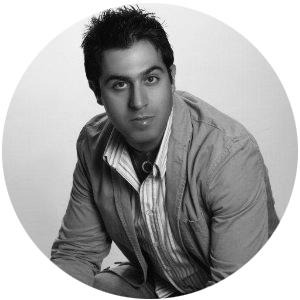
Reza Shiftehfar

Software Engineering Manager, Hadoop Platform, Uber

Reza Shiftehfar currently leads the Hadoop-Platform team at Uber where his team builds the required reliable/scalable data platform that serves petabytes of data utilizing technologies such as Hadoop, Hive, Kafka, Spark, Presto, etc. Reza is one of the founding engineers of the data at Uber and helped scale Uber's data platform from a few TB to 100+ PetaBytes while reducing the big data latency from 24+ hours down to minutes. Reza holds a Ph.D. degree in Computer Science from the University of Illinois @ Urbana-Champaign and had previously worked at Twitter and Apple on similar infrastructure/big data platforms. If you are interested in the area of distributed systems and Big Data analytics and want to follow up with Reza, you can reach him on LinkedIn (https://linkedin.com/in/reza-shiftehfar-39301b6/) or on Twitter (https://twitter.com/RezaSH).

Reza Shiftehfar

Sessions / 2018 / 2 talks

  • Uber’s mission is to provide transportation as reliable as running water, everywhere, and for everyone. To fulfil this mission, Uber relies heavily on making data-driven decisions at every level. Thus, we need to store more and more data as the business grows in addition to providing faster, more-reliable, and more-performant access to our analytical data. The Uber data platform is built around Hadoop ecosystem and stores more than 100 PetaBytes of data. This talk will dive into our Hadoop platform journey at Uber over the past few years, where we are standing now, and what we are building next. We started by emphasizing on data reliability, solved scalability and ease-of-use challenges and are currently focusing on faster data as well as improved efficiency.We'll look behind the scene at the current technology landscape at Uber including various big data solutions like Hadoop, Spark, Hive, Presto, Kafka, Avro, and Vertica as well as Uber's open-sourced applications and services such as Hudi, Marmaray, and Peloton. We'll dive into the technical aspect of how data freshness can be reduced from 24 hours down to minutes, ease-of-use be improved by adding a Hadoop dispersal service, GDPR regulatory requirements be addressed by providing update functionality for existing append-only columnar Hadoop data, and efficiency be improved by unifying ingestion services/pipelines. You’ll leave the talk with greater insight into how things work at Uber and will be inspired to re-envision your own data platform. In this talk we reflect on Uber’s journey with scaling our Data Infrastructure: how did we have to reinvent ourselves scaling from 1PB to 10PB to 100PB and beyond while reducing latency from 24 hours to 3h to 1h to 10 minutes, what tools did we have to make and open source to make this happen, and at what point should you think about building Data Platform.

  • Uber's mission is to provide transportation as reliable as running water, everywhere, and for everyone. To fulfill this mission, Uber relies heavily on making data-driven decisions at every level. Thus, we need to store an ever-increasing amount of data as the business grows in addition to providing faster, more-reliable, and more-performant access to our analytical data. In practice, this has resulted in 100+ PetaBytes of analytical data with minute-level data latency. On the other hand, due to Uber's global presence, regional regulations (such as GDPR) require additional and potentially more complex operations to be supported on the stored analytical data. These additional operations are usually unknown ahead of time, in many cases contradict the way data lakes are traditionally built/stored, and may require fundamental changes to the underlying assumptions/architecture. A good example is the GDPR regulation need to support update/delete operation on all historical Hadoop data that is traditionally considered append-only and stored in a read-only columnar file format within the analytical data lake. In this talk, we'll dive into how to build a generic big data platform that is flexible enough to support many of these unknown additional regulations/requirements out of the box and with minimum effort. This is not a review of how Uber tackled all the requirements of the GDPR but a deep dive into how Uber's big data platform came up with the fundamental primitives that enabled all other teams across the company to build their solution on top of Hadoop. We'll look into what technologies we were able to use from the open-source community (e.g. Hadoop, Spark, Hive, Presto, Kafka, Avro, and Vertica) and what solutions we had to build in-house (and open-source) to make this happen. You'll leave the talk with greater insight into how things work at Uber and will be inspired to re-envision your own data platform to make it more generic and flexible for future new requirements.

Ready to take this stage?

The next edition is programmed by practitioners. Tell us what you built and what you learned.

Apply to be a speaker