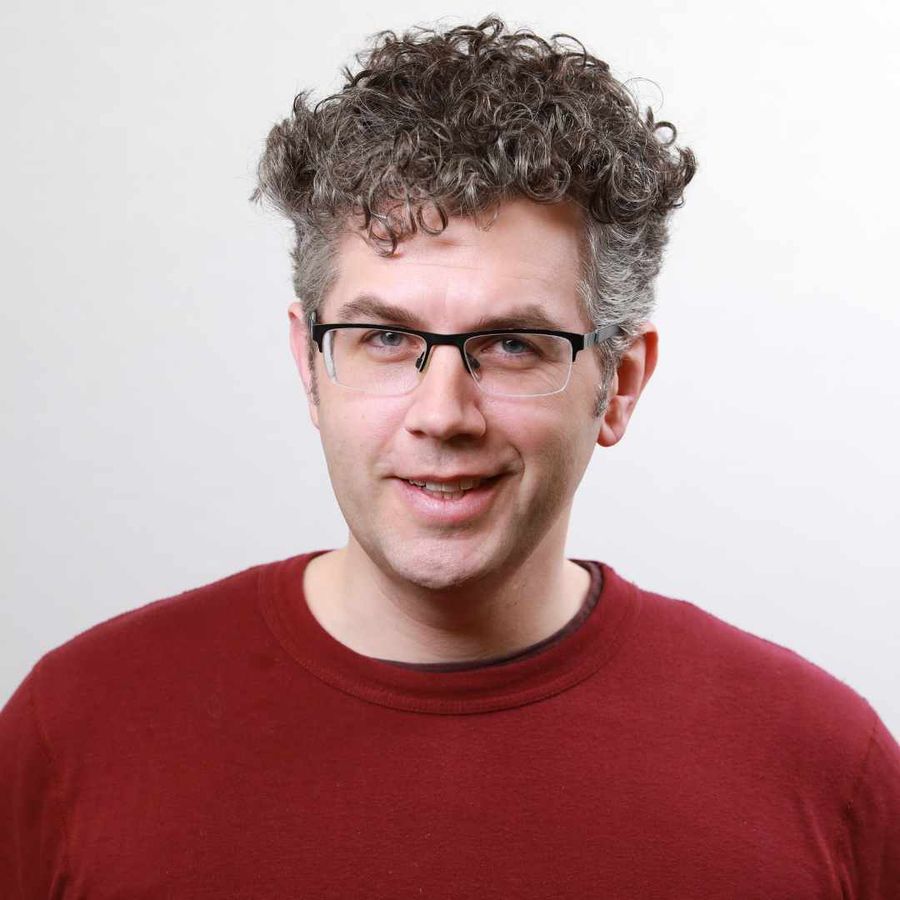
Frank McSherry

Chief Scientist, Materialize

Frank McSherry is Chief Scientist at Materialize, where he (and others) convert SQL into scale-out, streaming, and interactive dataflows. Before this, he developed the timely and differential dataflow Rust libraries (with colleagues at ETHZ), and led the Naiad research project and co-invented differential privacy while at MSR Silicon Valley. He has a PhD in computer science from the University of Washington.

Frank McSherry

Sessions / 2023 / 1 talk

  • A streaming database is a potentially intimidating thing to build. At Materialize, we've broken it down into what we feel are manageable parts, through three foundational choices that fit together well. The data are modeled as continually changing collections of records, as from *change data capture*, rather than ordered streams of events. The queries are standard SQL queries, whose answers are always "as if the query were continually re-executed on the data as it is now". The system architecture first assigns *virtual times* to both changed data and posed queries, and then computes the correct answers as fast as possible. In this talk, we will work through these three choices, the trade-offs, and how their simplifications lead us to a much more *manageable* streaming database.

Sessions / 2019 / 1 talk

  • At Materialize, Inc. we are building a high-throughput, low-latency SQL view maintenance engine. You write SQL queries against continually evolving relations, we give you back the answers fast. You ask the queries again and you get updated answers in milliseconds. This system design departs fundamentally from both Spark-like and relational database systems, and is based instead on timely dataflow and differential dataflow. In this talk, we will go through the architectural highlights distinguish Materialize from prior systems, call out how they enable interactive queries over continually evolving data, and demonstrate the stack used for real-time data warehousing.

Sessions / 2017 / 1 talk

  • The past years have seen a dramatic amount of work in the space of scalable computation frameworks, but how much progress have we actually made? We start with several well-known systems for graph processing and compare them against simple single-threaded implementations to find out just how much faster they can go. The answer, at least when we took the measurements, was that they don't go faster. That is, each was slower than a 10-15 line implementation on a laptop. This problem recurs in several areas of big data systems and research where weak baselines make new results seem like progress when they are just recovering ground lost in the initial excitement over Hadoop and Spark. We will trek through several such evaluations including the most recent systems coming out of the databases research community and provide a bit of advice and structure for the performance-minded.

Ready to take this stage?

The next edition is programmed by practitioners. Tell us what you built and what you learned.

Apply to be a speaker