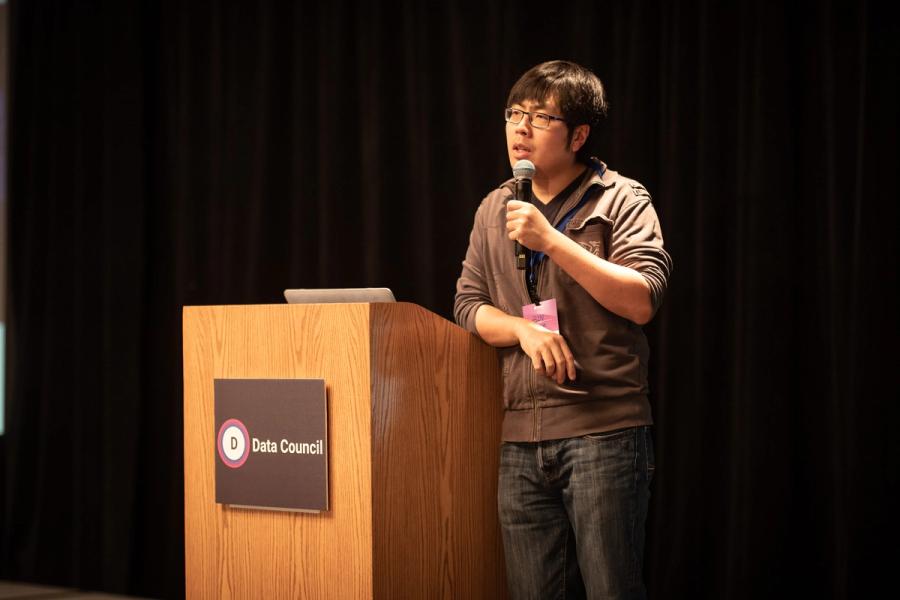
Bin Fan

Founding Member of Engineering, Alluxio Inc

Bin Fan is the founding engineer of Alluxio, Inc. and the PMC member of Alluxio open source project. Prior to Alluxio, he worked for Google to build the next-generation storage infrastructure. Bin received his Ph.D. in Computer Science from Carnegie Mellon University on the design and implementation of distributed systems and algorithms.

Bin Fan

Sessions / 2019 / 2 talks

  • Cloud has been dramatically changing the landscape of data engineering as well as the behavior of data engineers. Specifically, data storage is migrating from the colocated model (e.g., HDFS) to a more cost-effective, more scalable but often fully disaggregated and remote data lake model (e.g. AWS S3). This has also created a strong need for data orchestration in the cloud  like what Kubernetes does for container-based workloads, so that data can be presented in the right layout at the right location for data-consuming applications on the cloud. Originally developed from UC Berkeley AMPLab as research project "Tachyon", Alluxio (www.alluxio.io) implements the world’s first open-source data orchestration system in the cloud. Alluxio creates a unified access layer for data-driven applications in big data and ML, enabling Spark, Presto, TensorFlow and so on to transparently access different external storage systems while actively leveraging in-memory cache to accelerate data access. In this talk, the speaker will present: - New trends and challenges in the data ecosystem in the cloud era; - Effective data engineering in the cloud world with data orchestration; - Production use cases of using popular stacks like Presto/Alluxio/S3.

  • More big data and machine learning applications are built on top of the more scalable and cost-effective cloud storages (S3, Azure object store and etc), but trading off the benefit from traditional file systems like caching and data locality due to the separation of storage and compute. Alluxio (www.alluxio.org) is an open-source distributed file system that not only provides distributed applications like Presto and Apache Spark a common and unified data access layer to different data sources but also intelligently manages and places data and metadata closer to computation to improve performance. As a result, applications can seamlessly access multiple different data sources with consistent performance for data and metadata operations. Alluxio is originally a research project named “Tachyon” at UC Berkeley AMPLab. In this talk, we will focus on Alluxio design, its architecture, data flow and metadata flow. We will dive into the choices in its design space and share the experiences when implementing features like data tiering, storage options and cache eviction policies. We will also share our lessons in design, implementation and operation when working to build an open source distributed storage systems with 900 contributors for 5+ years.

Ready to take this stage?

The next edition is programmed by practitioners. Tell us what you built and what you learned.

Apply to be a speaker